
Business Process Automation Services
Most automations work in the demo and fail quietly on the hundredth run: a webhook arrives twice, an API times out, a record goes missing and nobody notices until the month-end close. We build and repair automations that retry safely, reconcile data, recover after failures and tell the process owner exactly what broke.
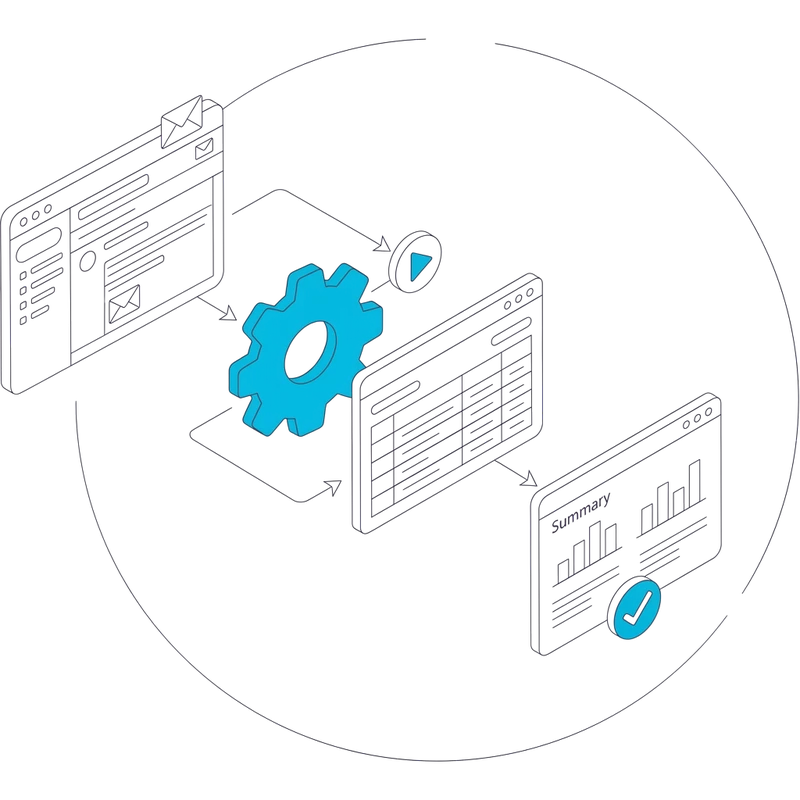
Signs your automation needs engineering
Connecting two services takes an afternoon. Keeping that connection correct for a year, at real volume, is the part we do.
- Orders or payments sometimes appear twice in the CRM or accounting, and someone removes the duplicates by hand
- A workflow stopped a week ago and you found out from a customer, not from an alert
- Numbers in the store, the warehouse and accounting never quite match, and a person reconciles them every month
- When a connected service goes down, the data from that hour is simply lost
- Dozens of Zapier or Make scenarios run the business, and nobody can say which of them still matter
- Leads, invoices or reminders are still copied between systems by hand because the last automation broke too often
What we build and fix
Process and failure audit
We map each process step by step, then look at how it fails: repeated events, timeouts, partial writes, missing records. You get a list of what to automate or fix, in order, with the risk of each item.
System integrations
Connections between CRM, ERP, accounting, stores, payment systems, email and messengers through APIs and webhooks. Writes are idempotent, so a repeated event never creates a second order or invoice.
Retries and recovery
Temporary errors are retried with backoff, and permanent ones go to a review queue instead of disappearing. After an outage, runs continue from where they stopped and missed events are replayed.
Data reconciliation
Scheduled checks compare records between systems, such as orders against payments or stock against the warehouse, and report every mismatch with a link to the record.
Logs, alerts and an owner
Every run is logged with its input and result. When something fails, the named owner of the process gets an alert that says what broke and which records are affected, in plain words.
Internal tools and bots
Admin screens and messenger bots for the steps that still need a person: approvals, exceptions and corrections. Built into the same flow, with change history.
The tool is the easy part
n8n, Make and Zapier are good tools, and we use them. n8n can also run on your own server when data must stay in your infrastructure. The tool decides how fast the first version appears. Whether the automation still works in six months depends on the engineering around it: what happens when the same webhook arrives twice, when an API is down for an hour, when a record is edited in two places at once. We design that part first, then pick the tool for each process, and write custom code where volume, logic or missing connectors make a no-code platform the wrong choice.
- Idempotent writes: a repeated event never creates a duplicate
- Retries with backoff for temporary errors, a review queue for permanent ones
- Self-hosted n8n when data must stay on your servers
- Custom services where connectors are missing or volumes are high
- Migration of overgrown Zapier or Make setups to something maintainable
Typical processes we automate
Most requests we get fall into a handful of patterns. Incoming leads are captured from forms, email and ads, checked for duplicates, assigned to a manager and answered with a first message. Orders are synchronised between the store, the warehouse and accounting, with stock updated in both directions. Invoices are generated from CRM deals and tracked until payment, with reminders. Each of these touches money or customers, so each gets the same treatment: no duplicates, no silent gaps and a way to replay what was missed.
- Lead intake and routing to the CRM
- Order and stock synchronisation between systems
- Invoicing, payment tracking and reminders
- Client and employee onboarding sequences
- Scheduled reports and alerts for management
When something breaks, the owner knows what and where
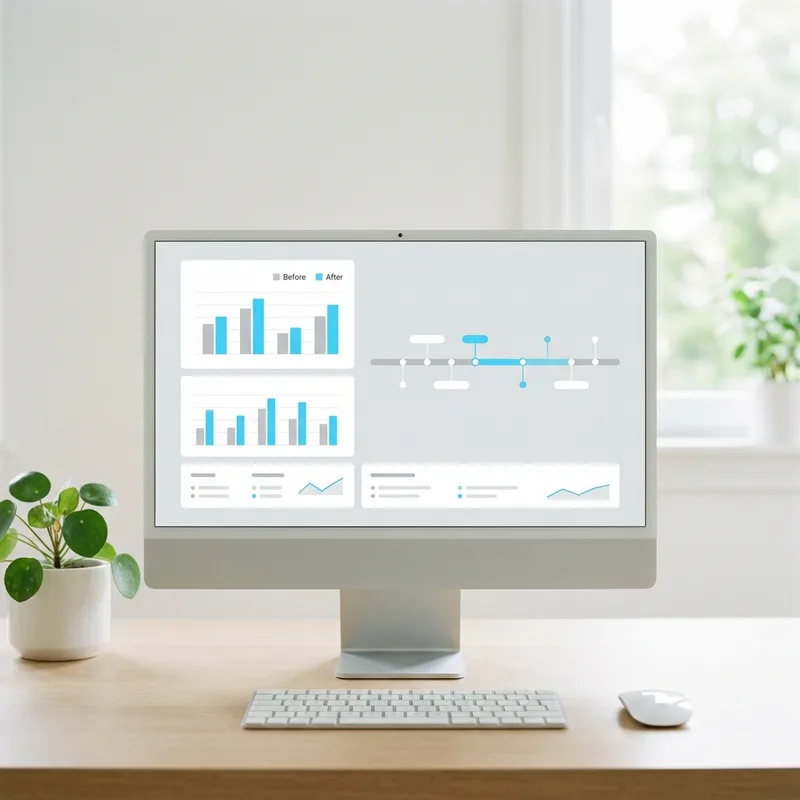
Every automation fails sometimes. What matters is whether it fails loudly. Each run we build is logged with what came in and what was written where. A failure sends an alert to a named person with the process, the step, the error and the affected records, instead of a red icon in a dashboard nobody opens. Reconciliation jobs compare the systems against each other on schedule, so a missed record shows up the next morning. We also record a baseline before launch, such as runs per week, minutes per run and errors found, and compare it with the logs afterwards, so the effect is measured rather than promised.
- Run history for every process, searchable by order, invoice or customer
- Alerts to the process owner by email or messenger, with the affected records
- Scheduled reconciliation between systems and a mismatch report
- A written runbook: how to replay missed events and how to roll back
How we work
Process audit
Interviews and screen-sharing sessions with the people who do the work, plus a look at how the current setup fails. You get a map of the processes, baseline numbers and a prioritised list.
Solution design
For each process: which systems are connected, which tool is used, what happens on duplicates, timeouts and outages, and who is alerted. You approve a short written design before we build.
Build and test
We build the workflows and integrations and run them on real data next to the manual process. We also break them on purpose: repeated events, a service switched off, a partial write.
Launch and handover
We switch the process over and hand over documentation, access and a runbook, so your team can check runs and handle simple issues themselves.
Support and next steps
We watch failures and mismatches, update integrations when a connected service changes its API, and report the measured effect. Then we pick the next process from the list.
Tools and technologies
Automation platforms
- n8n (cloud and self-hosted)
- Make
- Zapier
Custom development
- TypeScript and Node.js
- Python
- PHP / Laravel
- PostgreSQL, MySQL
- Queues and background workers
Reliability
- Idempotency keys and deduplication
- Retries with backoff
- Reconciliation jobs
- Run logs and alerts
Systems we connect
- CRM and ERP systems
- Accounting and invoicing
- Online stores and payment systems
- Google Workspace and email
- Telegram and other messengers
How we can work together
Fixed scope
One or several processes with an agreed design and result. Suits a clear task such as connecting the store to accounting or making lead intake reliable.
Dedicated team
A team that works through your automation list process by process and maintains what is already running. Suits companies with many systems and a growing back office.
Hourly
Audits and repairs of existing automations, small integrations and ongoing support. You pay for the time actually spent.
Related projects
See also: Business dashboards · AI integration · Web development · Server support · Website support
Reviews
We treat each client and his project with love.
Revol team continues to streamline the client’s development capabilities through their high-quality work and reliable support. They communicate effectively and exhibit a strong understanding of the client’s needs and business.
Tomas

The work from Revol, have fully met expectations and satisfied the client. Their fresh approach and ability to remain available for support have been valuable assets. Customers can bring them on for a communicative, client-oriented team to achieve their goals with.
Andrey
Frequently asked questions
Should we use n8n, Make, Zapier or custom code?
It depends on volume, complexity, data sensitivity and who will maintain it. Zapier and Make are quick for standard connections, n8n is more flexible and can run on your own server, and custom code makes sense for high volumes, unusual systems or core logic. The reliability rules are the same whichever tool runs the process.
Our Zapier or Make setup keeps breaking. Can you fix it without rebuilding everything?
Usually yes. We review the existing scenarios, document what each one does, add error handling, deduplication and alerts, and remove what is no longer needed. Only the parts that cannot be made reliable on their platform are rebuilt, and you get the reasons for each.
What happens when an automation fails?
Failed runs are logged, retried where it is safe, and reported to a named person with the affected records. Nothing fails silently. When the cause is fixed, the missed events are replayed, so the data catches up instead of staying lost.
How do you prevent duplicates?
Every write carries a key that identifies the event, and the receiving side checks it before creating anything. A webhook that arrives twice or a retry after a timeout then updates the same record instead of creating a second order, invoice or contact.
How do we know the automation was worth it?
We measure the process before we start: how often it runs, how long it takes, how many errors appear. After launch we compare the same numbers from the automation logs. You get real hours and error counts, not a promised percentage.
Who owns the accounts and the code?
You do. Automation platform accounts, servers and repositories are registered to your company, and we work with the access you give us. If you decide to maintain everything in-house later, nothing depends on us.
Where does AI fit into process automation?
Classic automation handles structured data and clear rules. When a step needs reading free-form emails, understanding documents or deciding where a request should go, an AI agent can take it over inside the same workflow. We describe this on our AI integration page and often add it as a second stage.
Tell us about your project
Describe the task in a few lines. Within one working day we reply with questions or a first view on scope and cost.
Prefer email or a call?
welcome@revolsource.com
+38 097 662 23 20
Revol Software OÜ, Tallinn, Estonia. Our team is distributed around the world.
Join our team
Send your CV to career@revolsource.com